Gemini vs ChatGPT vs Claude: We Scored 18 Months of Data. The Winner Depends on the Job.
Gemini vs ChatGPT vs Claude, scored on 18 months of leaderboards, 1,280 outages, benchmarks and prices. See which AI wins for coding, writing and more.

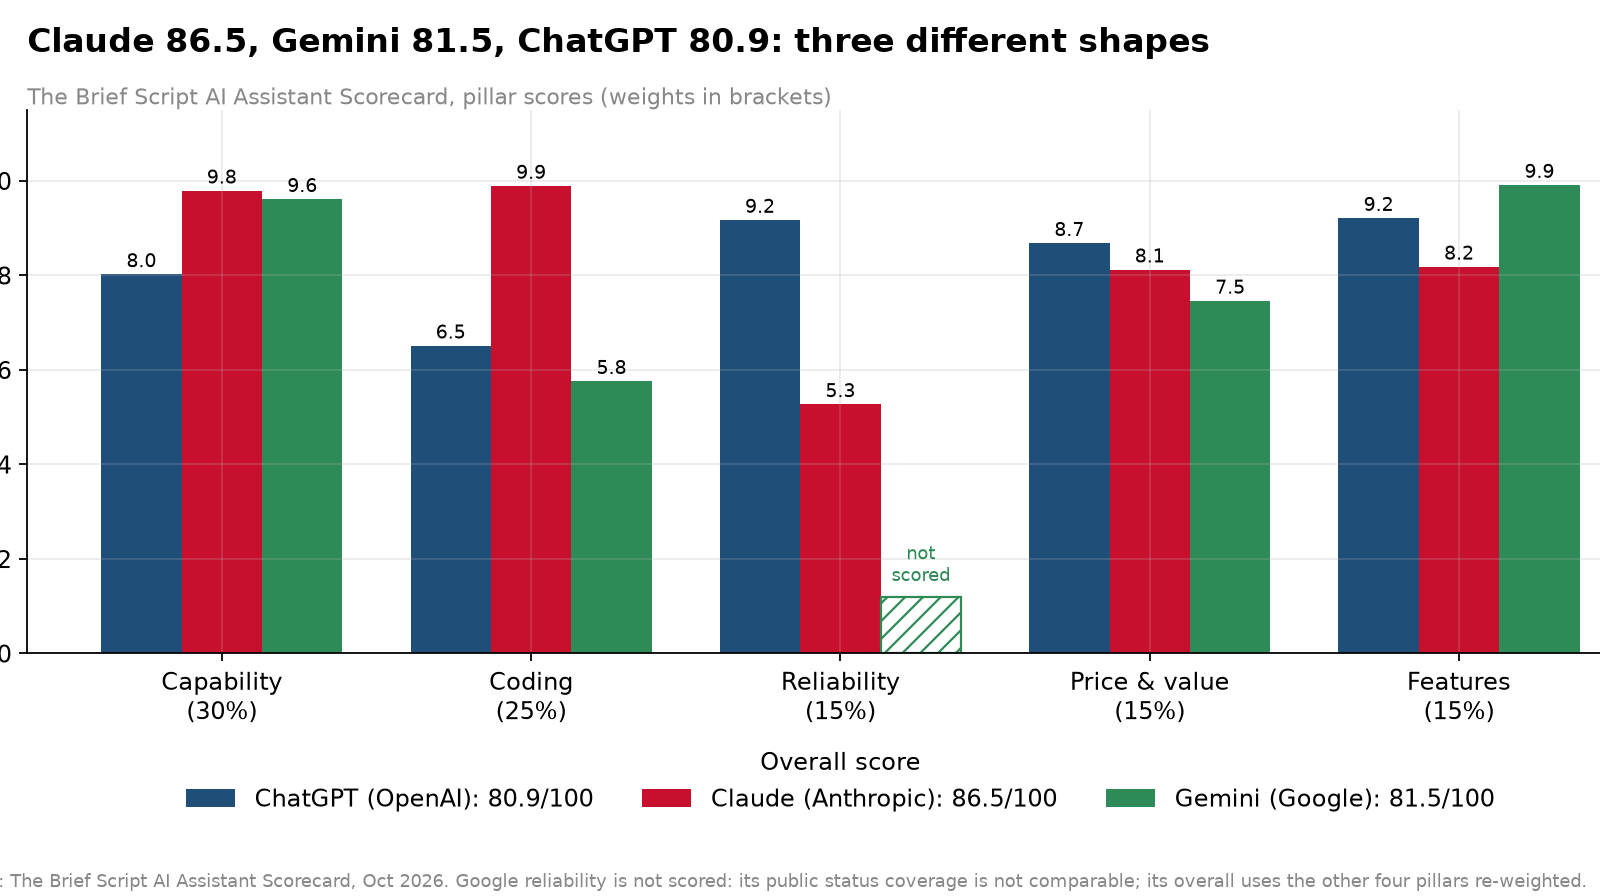
The Brief Script AI Assistant Scorecard, October 2026 edition. Original research by The Brief Script.
Updated October 2026: added head-to-head verdicts for Gemini vs ChatGPT, ChatGPT vs Claude and Claude vs Gemini, built from the same scorecard data.
Ask ten people whether ChatGPT, Claude or Gemini is “the best AI” and you’ll get ten confident answers, most based on a few chats and a viral chart.
We built an answer from data instead: 18 months of daily leaderboard history, every current benchmark score we could verify, 1,280 status-page incidents, and every plan the three companies sell. We combined it into one transparent scorecard, published the weights, and tried to break our own result. Every “current” comparison uses only models customers can still use as of October 25, 2026.
The short version of Gemini vs ChatGPT vs Claude in late 2026: Claude scores highest overall, but it’s not a runaway. ChatGPT is the most reliable and has the cheapest paid tier with current models. Gemini leads the main leaderboard today and has the most features. And on ChatGPT vs Claude for coding, human votes and hard tests don’t fully agree.
Only weighing two of them? Jump to the head-to-heads: Gemini vs ChatGPT, ChatGPT vs Claude or Claude vs Gemini.
Key takeaways
- Claude tops The Brief Script AI Assistant Scorecard with 86.5 out of 100, ahead of Gemini (81.5) and ChatGPT (80.9). Claude wins 15 of 20 alternative weightings, but only 40% of 10,000 random ones. Second place is a coin flip.
- Gemini is #1 on the main LMArena leaderboard today, but only just: Gemini 4 Argon leads Claude Opus 5.5 by 8.4 points, inside the margin of error.
- OpenAI hasn’t held the overall #1 spot since August 18, 2025. In the last 18 months Claude led for 240 days, Gemini for 234 and ChatGPT for 74.
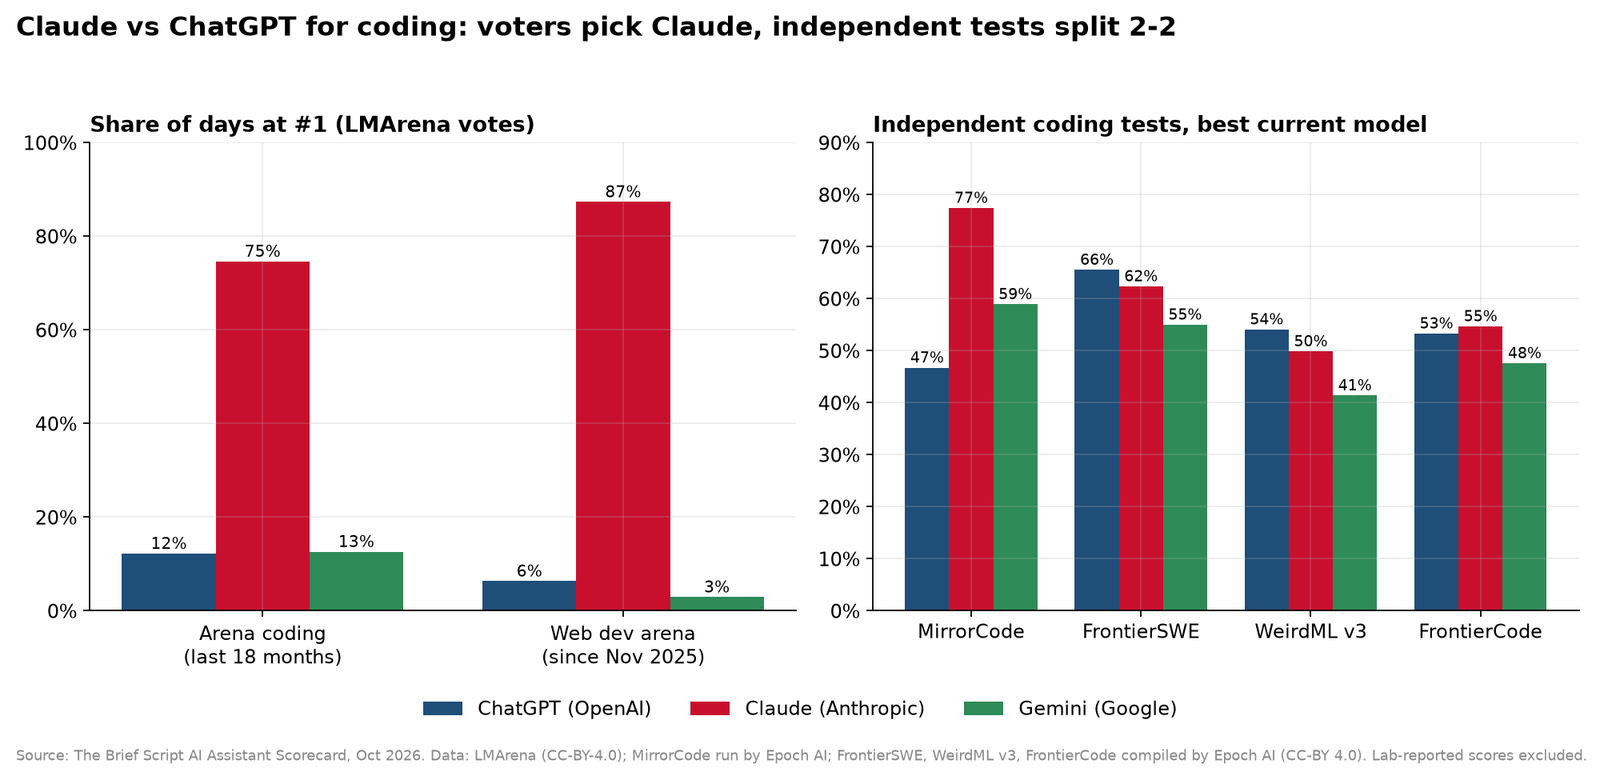
- Claude has owned coding. It held #1 in LMArena’s coding category for 409 of the last 548 days and in web development for 303 of 347 days. On four independent coding tests, though, Claude and ChatGPT split 2–2.
- ChatGPT’s models win the hard tests but lose the votes. OpenAI tops 5 of the 8 hardest benchmarks Epoch AI runs itself, yet its best entry ranks 21st on LMArena’s overall chart.
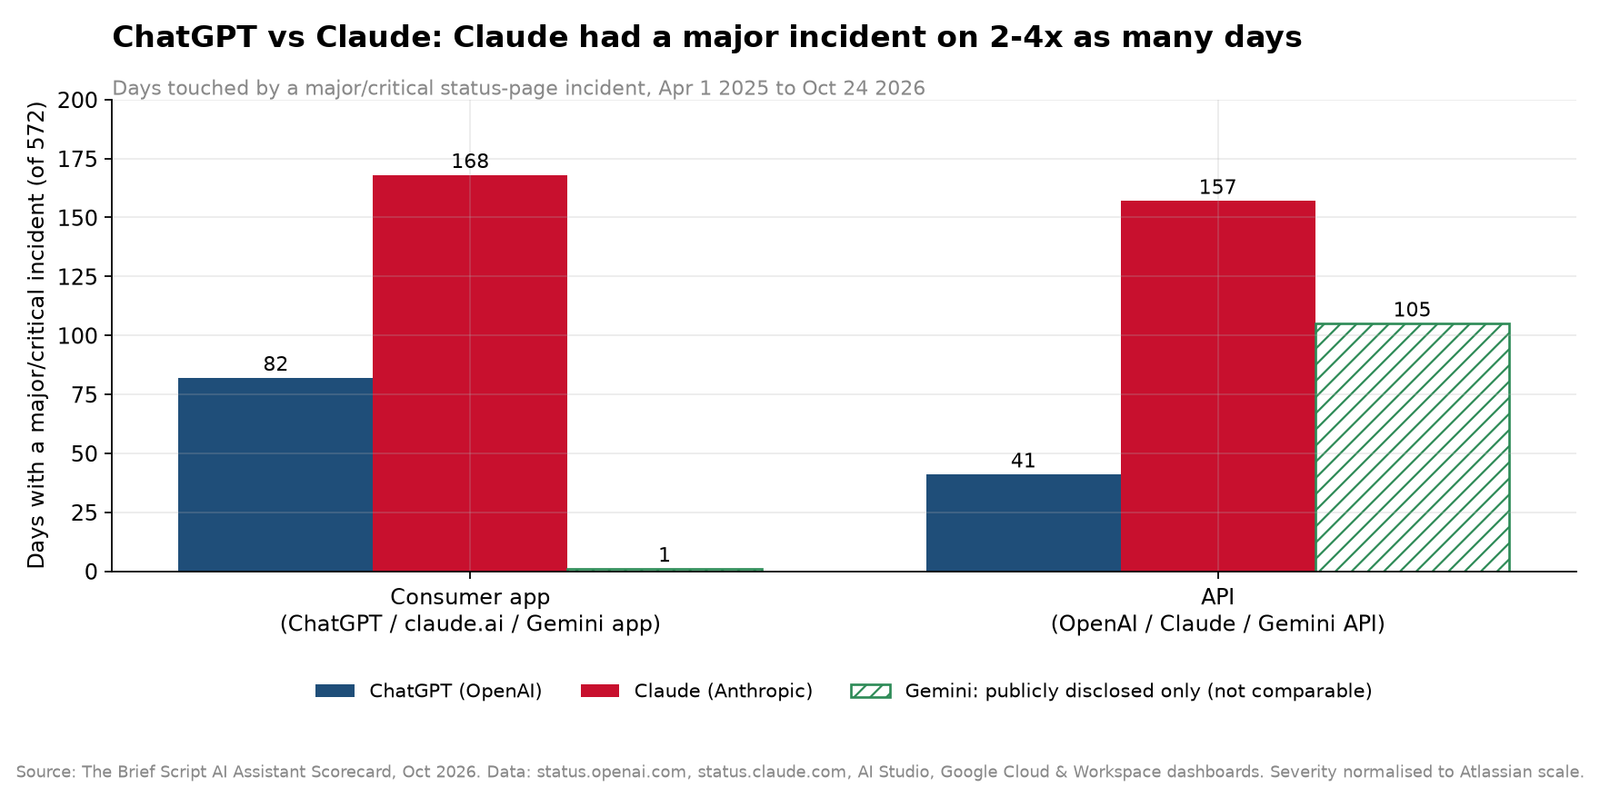
- On reliability, ChatGPT beats Claude clearly. Claude’s API had a major or critical incident on 157 of 572 days. OpenAI’s API had one on 41 days.
- The $20 plan is a three-way tie on price (ChatGPT Plus $20, Claude Pro $20 or $17 a month yearly, Google AI Pro $19.99). The differences are below and above it.
The short answer: which AI is best for what?
Each verdict comes from a sub-score built from this report’s data (method at the end).
| Use case | Winner | How clear? | Why |
|---|---|---|---|
| Coding | Claude | Clear | 75% of days at #1 in Arena coding, 87% in web dev; wins 2 of 4 independent tests |
| Writing | Claude | Narrow | #1 in creative writing and instruction following today; Gemini is within the margin of error |
| Research and knowledge | Claude (toss-up) | Narrow | Today the three are within 0.05 points; Gemini leads fact-recall tests, ChatGPT leads search |
| Math | ChatGPT | Split | Tops FrontierMath Tiers 1–3 and Tier 4; Claude has more days at #1 on Arena math |
| Budget | ChatGPT | Narrow | $8 Go plan, plus the cheapest strong API models |
| Business teams | ChatGPT | Clear (vs Claude) | Same seat price as Claude Team, a fraction of the major incidents |
| Free plan | ChatGPT | Narrow | Unlimited everyday chats; Gemini’s free tier is a close second |
| Images and video | Gemini | Clear | The only one that generates video; image generation on every plan, Free included |
Claude is the best maker (code, prose, precise instructions). ChatGPT is the safest all-rounder (uptime, a cheap paid tier, maths). Gemini is the most capable bundle (#1 on today’s leaderboard, the most features, the cheapest way in at $4.99).
What we built: The Brief Script AI Assistant Scorecard
The scorecard compares the three companies’ current lineups as of October 25, 2026, not single models. Each company gets credit for its best model that customers can still use on each test. We scored five pillars:
| Pillar | Weight | What goes in it |
|---|---|---|
| Capability | 30% | LMArena overall (18-month days at #1, today’s rating), Epoch Capabilities Index (ECI), eight benchmarks Epoch AI runs itself |
| Coding | 25% | Arena coding and web dev (days at #1, today’s rating), four independent coding tests |
| Reliability | 15% | Status-page incidents, April 2025 to October 2026: major/critical days (app, API), hours open, median length |
| Price and value | 15% | Cheapest paid plan, the ~$20 plan, cheapest API model at two capability levels |
| Features | 15% | 12-item checklist (~$20 plan), 6-item checklist (free plan) |
Every metric is scored 0 to 10 against the best of the three. Inside each pillar, related metrics form blocks (in coding: track record, today’s votes, independent tests) that count equally. Full rules are in the Methodology.
| Capability | Coding | Reliability | Price & value | Features | Overall | |
|---|---|---|---|---|---|---|
| Claude (Anthropic) | 9.8 | 9.9 | 5.3 | 8.1 | 8.2 | 86.5 |
| Gemini (Google) | 9.6 | 5.8 | not scored* | 7.5 | 9.9 | 81.5 |
| ChatGPT (OpenAI) | 8.0 | 6.5 | 9.2 | 8.7 | 9.2 | 80.9 |
*Google’s public status pages aren’t comparable (more below), so Gemini’s overall re-weights the other four pillars.
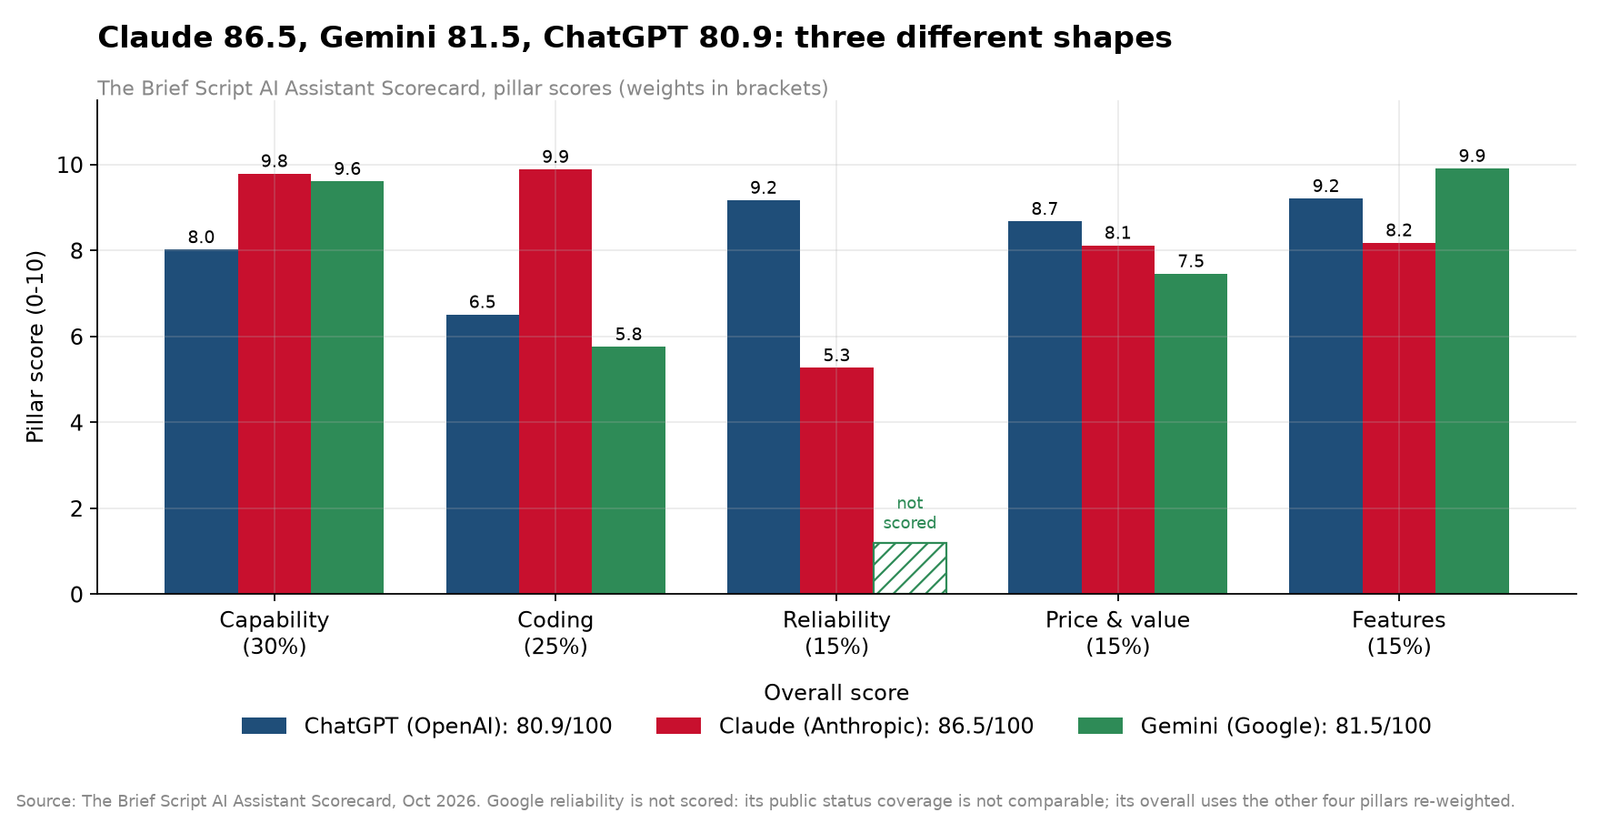
Look at the shapes. Claude is near-perfect on capability and coding, weak on reliability. ChatGPT is the reverse. Gemini has the most features and near-top capability, but the lowest coding score.
Gemini vs ChatGPT
Verdict: effectively a tie overall, with clear lanes. Gemini wins on everyday chat as judged by voters, features and the cheapest way in. ChatGPT wins on reliability we can measure, hard maths and coding. Gemini scores 81.5 on our scorecard, ChatGPT 80.9, and Gemini finishes ahead in 9 of our 20 weighting scenarios.
- Human votes: Gemini. Gemini 4 Argon is #1 on LMArena (1517.2); OpenAI’s best available entry is 21st (1485.1). Over the last 18 months Gemini held #1 for 234 days, OpenAI for 74.
- Hard tests: ChatGPT, mostly. On Epoch AI’s own runs OpenAI leads FrontierMath Tier 4 (100% vs 78.0%) and Tiers 1–3 (93.7% vs 86.0%). Gemini edges GPQA Diamond (96.4% vs 95.8%) and SimpleQA Verified (76.0% vs 75.6%).
- Coding: ChatGPT. OpenAI’s best model beats Gemini 4 Argon on three of four independent coding tests (FrontierSWE: 65.5% vs 55.0%; Gemini takes MirrorCode), and GPT-6 Astra is 2nd on today’s web-dev chart to Gemini’s 11th. Coding pillar: 6.5 vs 5.8.
- Features and entry price: Gemini. 11 of 12 checklist points to ChatGPT’s 9.3, the only native video generation, and Google AI Plus at $4.99 against ChatGPT Go at $8. The ~$20 tier is a wash ($19.99 vs $20).
- Reliability: ChatGPT by default. OpenAI scores 9.2 on reliability. Google’s public status pages aren’t comparable, so Gemini isn’t scored here.
Pick Gemini for everyday chat, research lookups, images and video. Pick ChatGPT for maths, code and anything that has to stay up.
ChatGPT vs Claude
Verdict: Claude for making things, ChatGPT for running things. Claude leads our scorecard 86.5 to 80.9 and finishes ahead of ChatGPT in 16 of 20 weighting scenarios, on the strength of coding and writing. ChatGPT wins the other three pillars and has no weak spot.
- Pillars: Claude wins capability (9.8 vs 8.0) and coding (9.9 vs 6.5). ChatGPT wins reliability (9.2 vs 5.3), price and value (8.7 vs 8.1) and features (9.2 vs 8.2).
- Coding: Claude held #1 in Arena coding for 409 of the last 548 days, against 67 for OpenAI, and leads today’s web-dev chart (1806.9 vs 1774.3). Independent tests split 2–2: Claude takes MirrorCode by 30.7 points, ChatGPT takes FrontierSWE (65.5% vs 62.3%).
- Reliability: OpenAI’s API had a major or critical incident on 41 days in 18 months, Claude’s on 157; on the consumer apps it was 82 days vs 168. Claude fixes things faster (median 1.10 hours vs 1.65).
- Maths: ChatGPT. GPT-6.1 Sol scores 100% on FrontierMath Tier 4 to Claude’s 95.0%.
- Price: both charge $20 for the main plan, but Claude Pro drops to $17 a month billed yearly, and only ChatGPT has a cheaper tier (Go, $8). Team seats cost the same: $20 a month billed yearly.
Pick Claude if you code or write for a living. Pick ChatGPT for a business-wide rollout, a production API or a tight budget.
Claude vs Gemini
Verdict: the closest race on raw ability, decided by what you do with it. Claude leads our scorecard 86.5 to 81.5 and finishes ahead in 17 of 20 weighting scenarios, almost entirely because of coding. On general capability the two are nearly level.
- Leaderboard: a dead heat. They split overall #1 over 18 months (Claude 240 days, Gemini 234), and today’s 8.4-point Gemini lead (1517.2 vs 1508.7) is inside the margin of error.
- Capability: 9.8 vs 9.6. On Epoch’s index, Claude Opus 5.5 (168.83) and Gemini 4 Argon (166.45) have overlapping confidence ranges. Gemini wins GPQA Diamond and SimpleQA; Claude wins FrontierMath and the puzzle tests.
- Coding: Claude, clearly. Coding pillar 9.9 vs 5.8; Claude beats Gemini on all four independent coding tests (MirrorCode: 77.4% vs 58.9%) and leads web dev at 1806.9 to Gemini’s 1674.2 (11th). Gemini’s one coding win: a 1.0-point lead in Arena coding today.
- Features: Gemini, 11 checklist points to 9. It generates images and video; Claude does neither. Both offer up to 1M tokens of context on the ~$20 plan.
- Price: $20 vs $19.99 for the main plan. Gemini has a $4.99 tier; Claude has nothing below $20 but a $17 yearly rate. On the API both sell frontier-level models for $4 per million blended tokens, though Gemini 4 Argon’s promotional price doubles on December 1, 2026.
Pick Claude for code, writing and long documents on a free plan (up to 1M tokens of context vs Gemini Free’s 32K). Pick Gemini for images, video, fact-heavy research and the cheapest paid entry.
Finding 1: Claude leads, but the lead depends on what you value
A scorecard is only as good as its weights, so we re-ran ours 20 ways: equal weights, each pillar dropped or boosted, two other normalisations, and best and worst cases for Google’s missing reliability score.
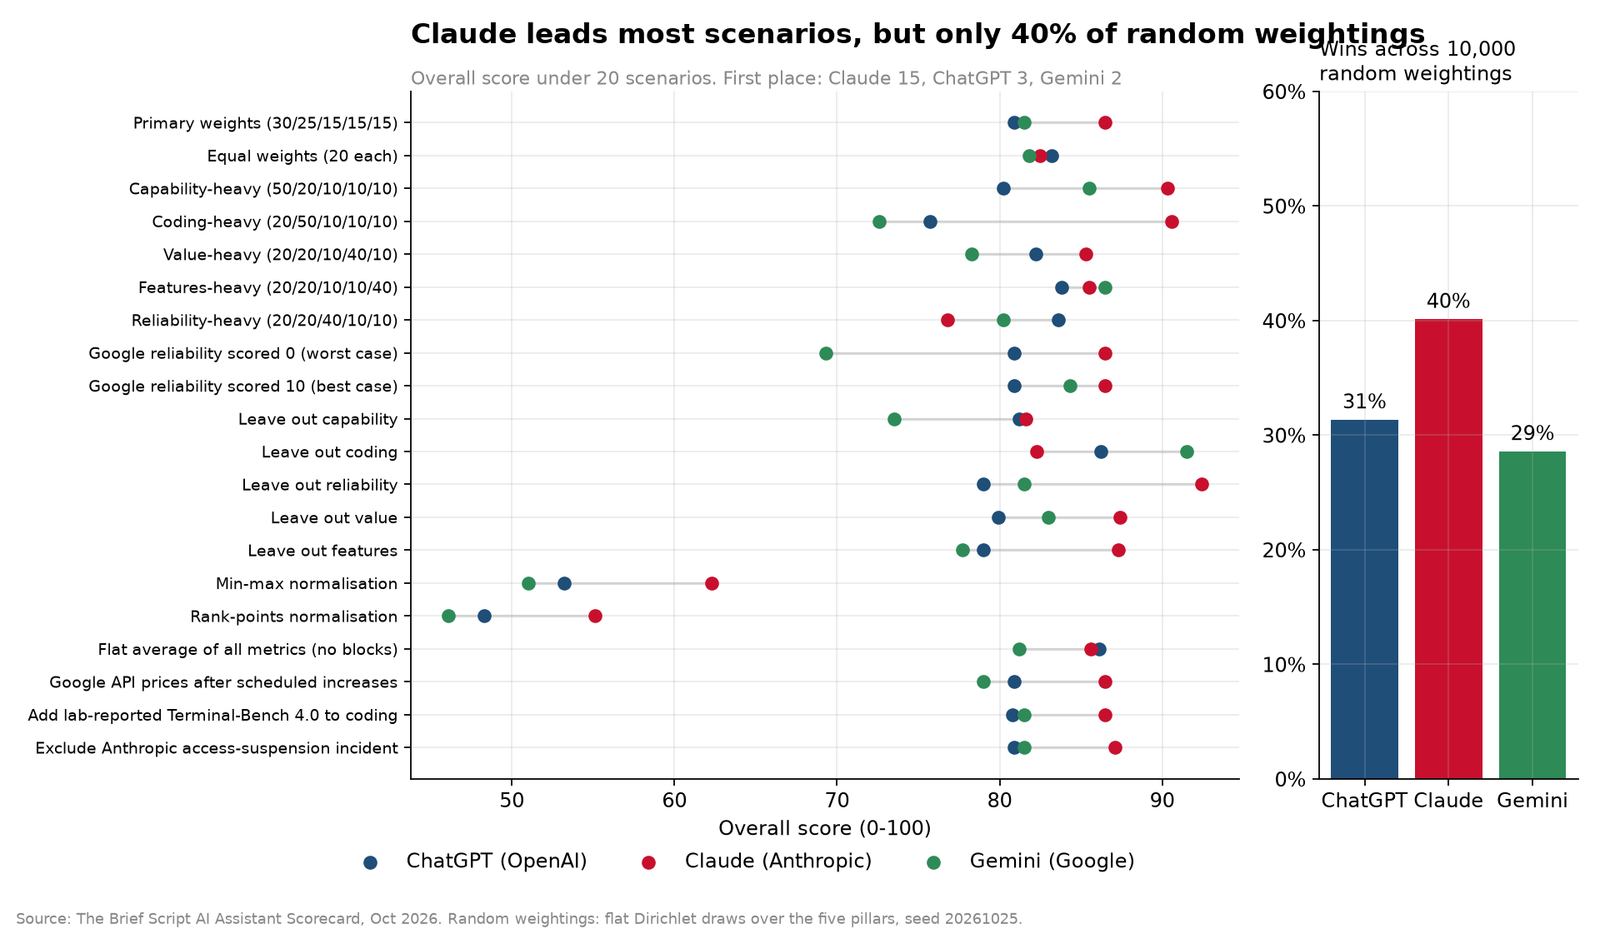
Claude finishes first in 15 of the 20 scenarios. ChatGPT wins 3 (equal weights, reliability-heavy, and a flat average with no blocks). Gemini wins 2 (features-heavy, and leaving coding out).
Across 10,000 random sets of weights, Claude wins 40%, ChatGPT 31% and Gemini 29%. Claude wins whenever coding or capability carries real weight. But it has a clear weak spot in reliability, while ChatGPT has no weak pillar.
Second place is even less settled: Gemini (81.5) and ChatGPT (80.9) are 0.6 points apart, and Gemini finishes ahead in 9 of the 20 scenarios and behind in 11.
What this means: Code or write for a living? Claude. Uptime first? ChatGPT. Most for your money in one subscription? Gemini. Pick your weights, then your assistant.
Finding 2: Gemini vs ChatGPT on the leaderboard: Google took the crown OpenAI used to own
LMArena (formerly Chatbot Arena) ranks models by millions of blind, head-to-head human votes. We rebuilt its history from the public dataset: 11,427 rows, January 2024 to October 2026.
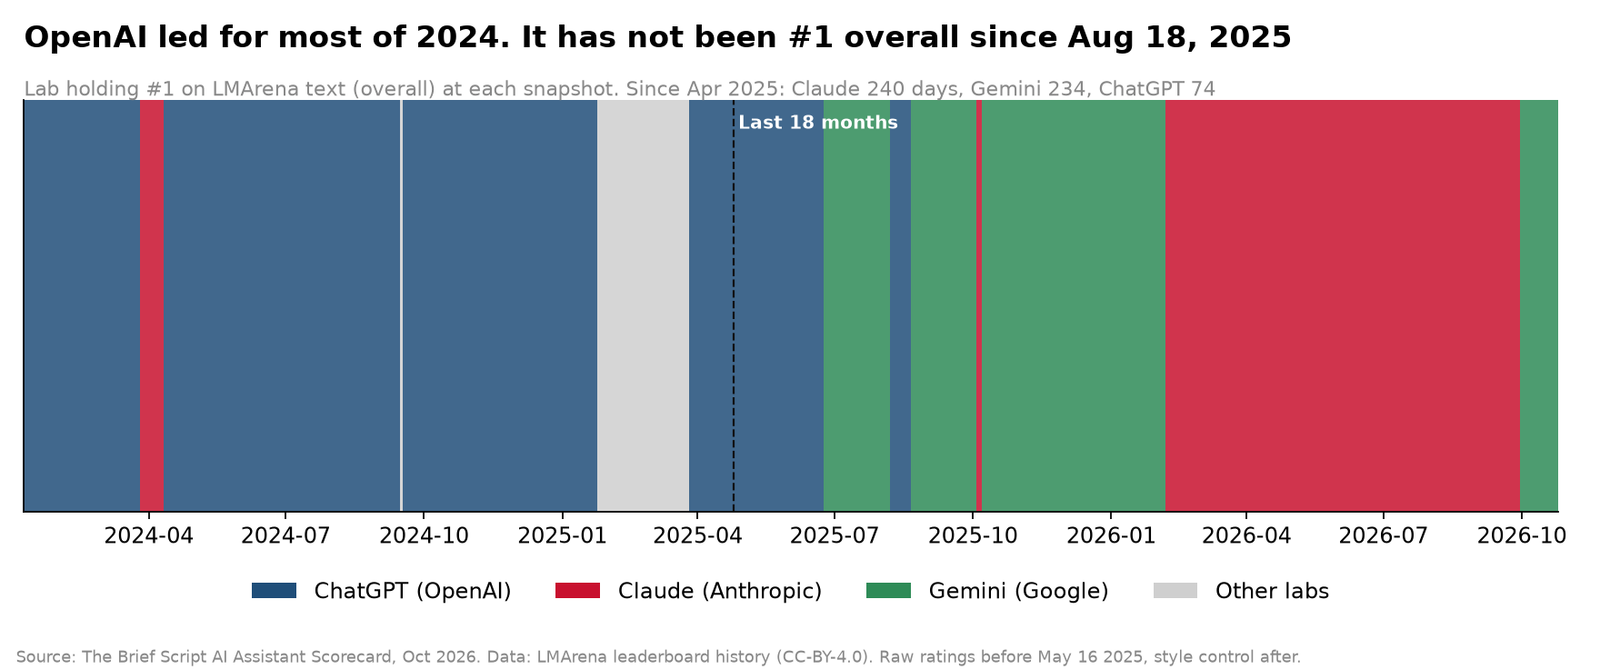
Since January 9, 2024, OpenAI still has the most days at #1 overall (467 of 1,020, 45.8%), mostly from the GPT-4o and o1 era. But its last day at #1 was August 18, 2025, with GPT-5-high.
The last 18 months (April 25, 2025 to October 25, 2026) have been a two-horse race:
| Lab | Days at #1, text overall | Share |
|---|---|---|
| Anthropic (Claude) | 240 | 43.8% |
| Google (Gemini) | 234 | 42.7% |
| OpenAI (ChatGPT) | 74 | 13.5% |
No other lab held #1 in that window.
Right now, Gemini is on top by a statistical hair. On the October 22, 2026 snapshot, Gemini 4 Argon (High) scored 1517.2 and Claude Opus 5.5 (High) 1508.7, a gap inside both 95% confidence intervals.
OpenAI’s best available entry, GPT-5.6 Sol (xHigh), sits at 1485.1, rank 21; its flagship GPT-6 Astra (Max) is at 1476.5, rank 32. Voters would pick Gemini 4 Argon over OpenAI’s best about 55% of the time.
Gemini is also #1 today in hard prompts, longer queries, multi-turn chats and math. Claude is #1 in creative writing, instruction following, expert prompts, vision and web development. OpenAI leads only search, where it has held #1 for 219 of 444 days.
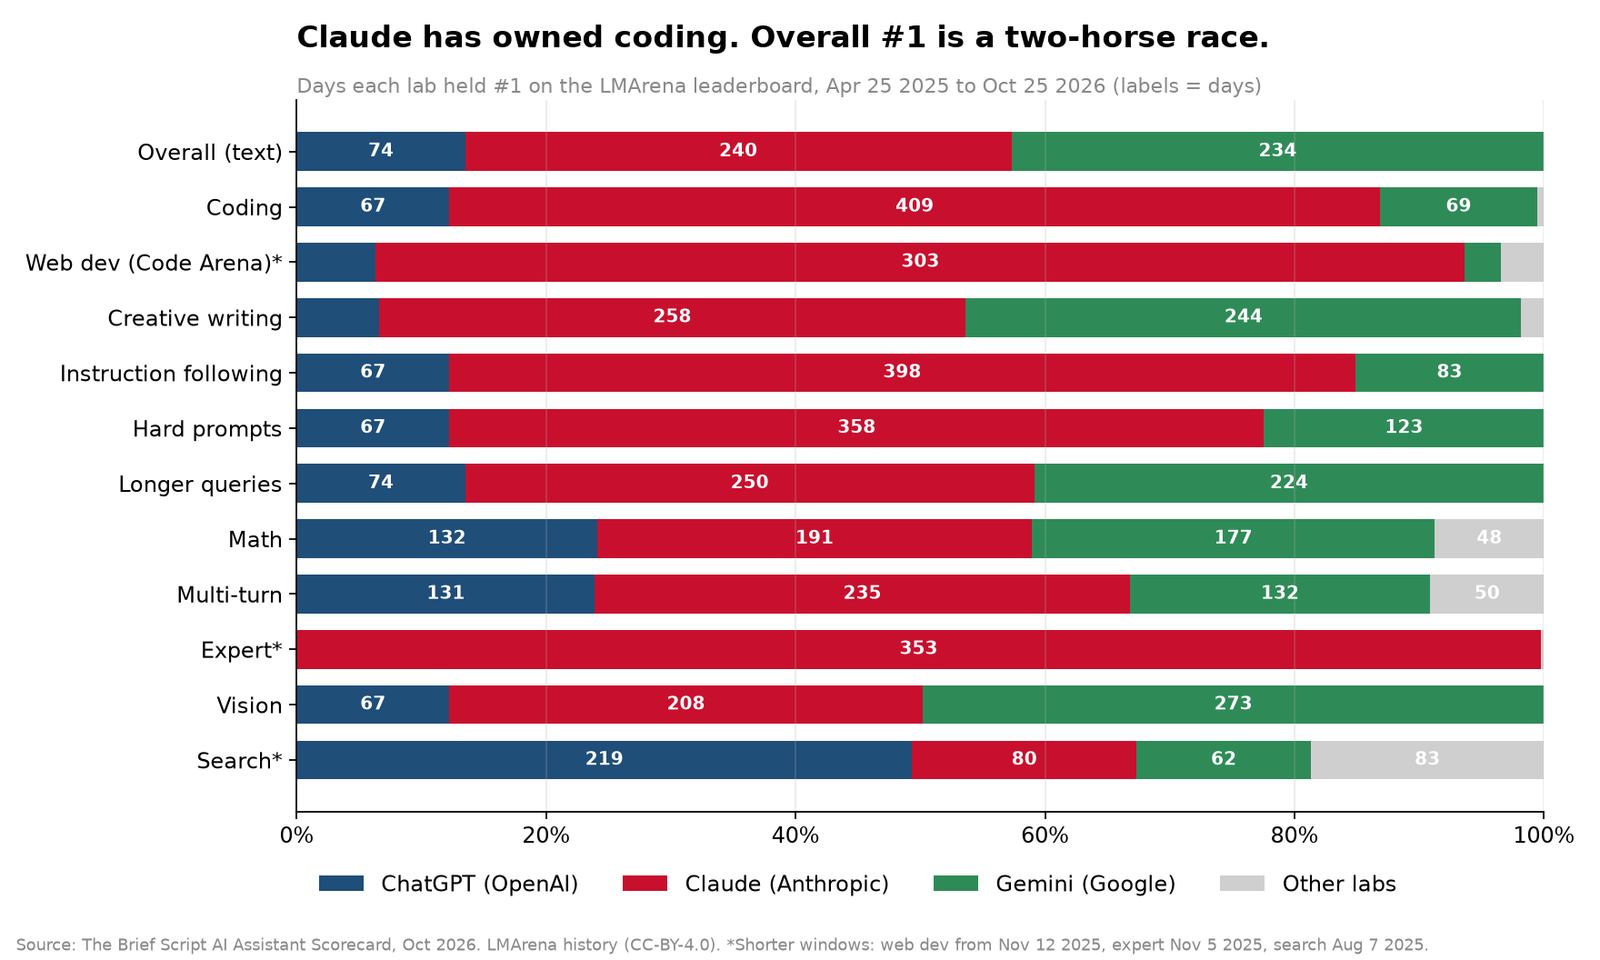
What this means: On Gemini vs ChatGPT for everyday chat as judged by users, Gemini wins now and has won far more often. Claude vs Gemini is genuinely close.
Finding 3: Claude vs ChatGPT for coding: votes and tests disagree
Most answers to “claude vs chatgpt for coding” say Claude. The votes agree, emphatically:
- Arena coding: Anthropic held #1 for 409 of 548 days (74.6%), against 69 for Google and 67 for OpenAI.
- Web development (Code Arena): Anthropic held #1 for 303 of 347 days (87%) since November 2025.
- Today’s web-dev chart: Claude Opus 5.5 (Max) leads at 1806.9, GPT-6 Astra (Max) is second at 1774.3, and Gemini 4 Argon is 11th at 1674.2.
But the crown is contested. Gemini 4 Argon took Arena coding #1 on September 30, 2026; it leads Claude Fable 5 by 1.0 point (1551.6 vs 1550.6), with GPT-6 Astra (Max) within the margin of error at 1543.1. Independent tests are more mixed:
| Independent coding test | ChatGPT (best model) | Claude (best model) | Gemini (best model) |
|---|---|---|---|
| MirrorCode (Epoch AI run) | 46.7% (GPT-6 Astra) | 77.4% (Opus 5.5) | 58.9% (Gemini 4 Argon) |
| FrontierSWE | 65.5% (GPT-6 Astra) | 62.3% (Opus 5.5) | 55.0% (Gemini 4 Argon) |
| WeirdML v3 | 54.1% (GPT-6 Astra) | 49.8% (Opus 5.5) | 41.4% (Gemini 4 Argon) |
| FrontierCode | 53.3% (GPT-6 Astra) | 54.6% (Opus 5.5) | 47.6% (Gemini 4 Argon) |
Claude wins two, ChatGPT two, Gemini none. Claude’s MirrorCode lead (30.7 points over GPT-6 Astra) is the biggest margin in the table.
On the labs’ own Terminal-Bench 4.0 figures, Anthropic reports 70.6% for Claude Sonnet 5.5 and 66.4% for Opus 5.5, against OpenAI’s 57.9% for GPT-6 Astra and Google’s 57.4% for Gemini 4 Argon. These are lab-reported under each lab’s setup, and the labs disagree on each other’s numbers (Google lists GPT-6 Astra at 58.2%), so we leave them out of the score. Adding them doesn’t change the winner. The old standard, SWE-bench Verified, is effectively retired: no lab published it for current models.
What this means: For ChatGPT vs Claude on code, Claude is the safer default, especially for web front ends. GPT-6 Astra is a real alternative on algorithmic work. Test both on your own repo.
Finding 4: ChatGPT wins the hard tests, then loses the vote
On the eight hardest benchmarks Epoch AI runs itself (not lab claims), OpenAI’s current models come top in five:
| Benchmark (Epoch AI’s own run) | ChatGPT | Claude | Gemini |
|---|---|---|---|
| FrontierMath Tiers 1–3 | 93.7% | 91.2% | 86.0% |
| FrontierMath Tier 4 | 100% | 95.0% | 78.0% |
| Chess Puzzles | 76.0% | 67.0% | 59.0% |
| Mystery Game Puzzles | 84.0% | 71.0% | 64.0% |
| EBR-bench | 76.2% | 71.4% | 64.8% |
| GPQA Diamond (PhD-level science) | 95.8% | 95.6% | 96.4% |
| SimpleQA Verified (factual recall) | 75.6% | 72.2% | 76.0% |
| Furniture Assembly | 80.0% | 83.3% | 72.5% |
Best current model per company (e.g. FrontierMath Tier 4: GPT-6.1 Sol; GPQA and SimpleQA: Gemini 4 Argon; Furniture Assembly: Claude Opus 5.5).
So why does OpenAI rank 21st with voters? Arena ratings measure preference (tone, formatting, helpfulness on everyday prompts); benchmarks measure whether hard, checkable answers are right. On this evidence OpenAI builds superb problem solvers that people currently like chatting with less.
On Epoch’s composite Epoch Capabilities Index (ECI), the top is a dead heat:
| Model | ECI | 95% CI |
|---|---|---|
| Claude Opus 5.5 | 168.83 | 165.25–173.95 |
| GPT-6 Astra | 168.81 | 165.45–174.51 |
| GPT-6.1 Sol | 168.37 | 165.00–174.43 |
| Claude Fable 5.1 | 166.49 | 163.47–171.35 |
| Gemini 4 Argon | 166.45 | 163.23–171.52 |
All five ranges overlap: a three-way tie.
What this means: For the best AI model in 2026 at maths, science or logic, the evidence leans to OpenAI: GPT-6.1 Sol solved every problem in FrontierMath Tier 4. For day-to-day enjoyment, votes lean to Gemini and Claude.
Finding 5: ChatGPT vs Claude on reliability: OpenAI is clearly steadier
We pulled every public status-page incident from April 1, 2025 to October 24, 2026 (572 days): 564 for OpenAI, 654 for Anthropic and 62 for Google, 1,280 in total. Raw counts mislead, so we lead with days a user would have hit a major or critical problem.
| Measure (Apr 2025 – Oct 2026) | ChatGPT / OpenAI | Claude / Anthropic |
|---|---|---|
| Consumer app: days with a major or critical incident | 82 | 168 |
| API: days with a major or critical incident | 41 (7% of days) | 157 (27% of days) |
| Hours with a major or critical incident open (all products) | 502 | 1,397 |
| Share of incidents rated major or critical | 18% | 33% |
| Median incident length | 1.65 h | 1.10 h |
Claude’s app had a major or critical incident on about twice as many days as ChatGPT’s, its API on almost four times as many. In Anthropic’s defence, it fixes things faster and posts in more detail: 379 of its 654 incident titles (58%) name a specific model, inflating raw counts but not day counts.
Anthropic’s longest “incident” was a 450.6-hour suspension of Claude Mythos 5 and Claude Fable 5 from June 13, 2026, under a US export-control order, not an outage; both returned July 1. Leaving it out cuts Anthropic’s major-incident hours from 1,397 to 952, still almost double OpenAI’s, and the scorecard result doesn’t change.
What about Gemini? Google’s numbers can’t be compared, so we don’t score them. The consumer Gemini app has no public status page. Google’s Workspace dashboard listed 6 Gemini incidents in 19 months; the hand-curated AI Studio and Vertex feeds list 56, touching 105 days, with a median of 4.84 hours. That is what Google disclosed, not what happened.
What this means: For products built on an AI API, OpenAI’s 18-month record is clearly better. If you run Claude in production, build in retries and a fallback model.
Finding 6: Same $20 middle, very different ladders
At the tier most people buy, price is a non-issue. ChatGPT Plus is $20 a month (unchanged since February 2023, monthly only). Claude Pro is $20, or $17 a month billed yearly ($200), the only verified annual discount. Google AI Pro is $19.99, unchanged since February 2024. The differences are on either side.
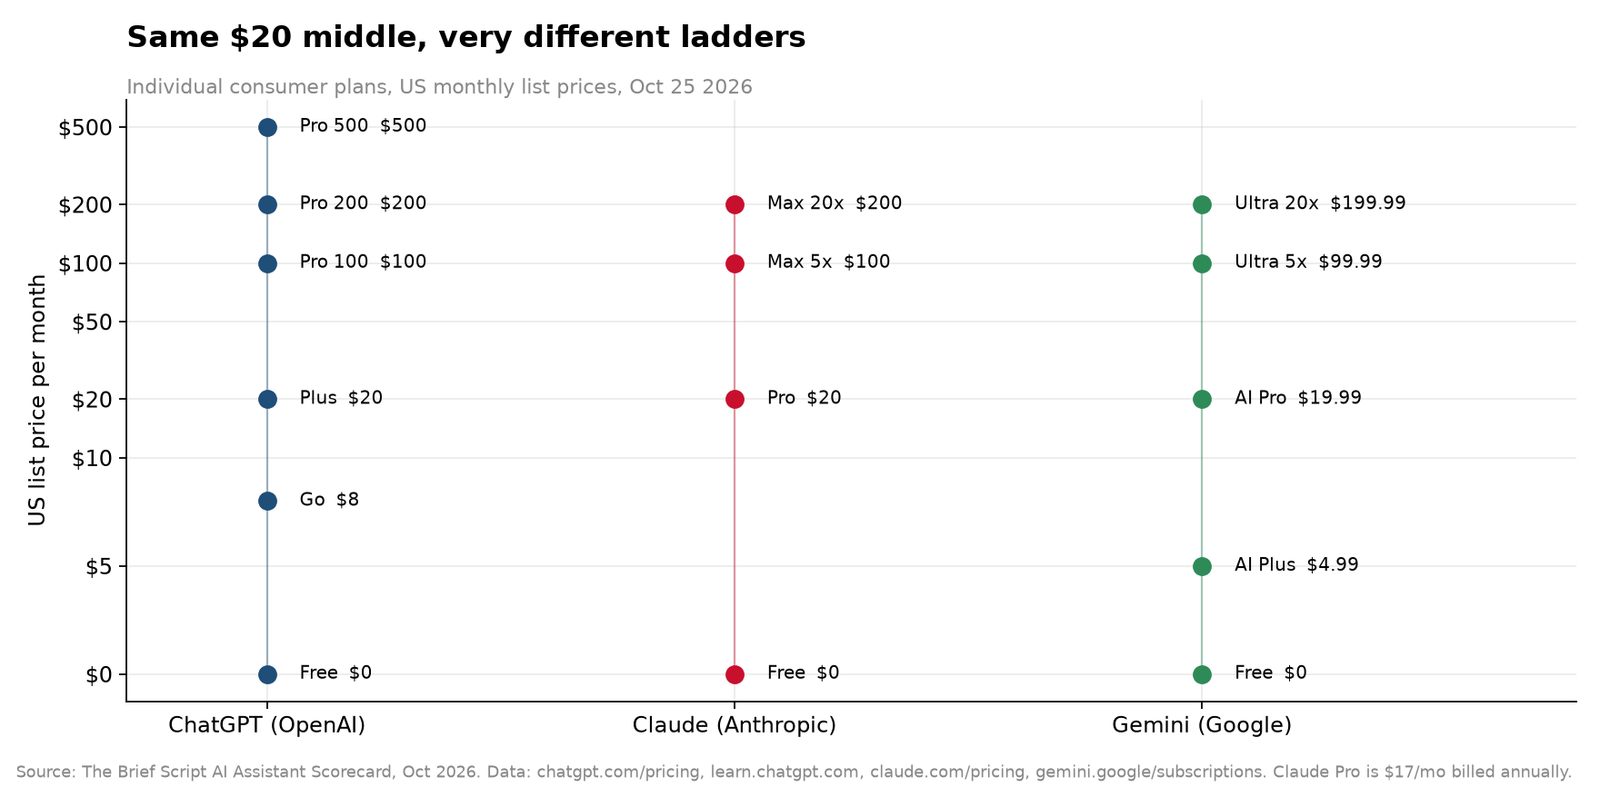
Below $20, ChatGPT has Go ($8) and Google AI Plus ($4.99, cut from $7.99 around June 2026). Claude has nothing.
Above $20, all three sell ~$100 and ~$200 tiers; OpenAI adds Pro 500 at $500 a month, 25 times its $20 tier (Claude’s and Google’s tops are 10 times).
For teams, prices have converged. ChatGPT Business and Claude Team both charge $20 per seat a month billed yearly, or $25 monthly, after cuts from $25 this year (April 2 and January 28, 2026). Gemini Enterprise’s Business edition starts at $21.
For developers, the cheapest model scoring 166+ on ECI (frontier level) costs $4 per million blended tokens at all three: GPT-6.1 Sol, Claude Sonnet 5.5 and Gemini 4 Argon. But Argon’s price is promotional and doubles to $8 on December 1, 2026. One tier down (ECI 155+), GPT-6 Luna and Claude Haiku 5.5 cost $0.20 (Haiku for prompts up to 100K tokens), against $1.50 for Gemini 3.8 Flash, also due to double on January 1, 2027.
What this means: Choose on what’s below and above $20. ChatGPT Go ($8) or Google AI Plus ($4.99) gets you in cheaper; heavy coders live in the $100 to $200 tiers.
Finding 7: Gemini has the most features. Claude still has the biggest free context window
On our 12-item checklist for the ~$20 plan, Gemini scores 11 points, ChatGPT 9.3 and Claude 9.
All three offer voice, deep research, memory, app connectors, custom assistants, a computer-use agent and a coding agent (Codex, Claude Code, Jules). The gaps:
| Feature (~$20 plan) | ChatGPT Plus | Claude Pro | Google AI Pro |
|---|---|---|---|
| Context window | 256K (reasoning) | Up to 1M | 1M |
| Image generation | Yes | No | Yes |
| Video generation | Not listed | No* | Yes |
| Annual discount | No | Yes ($17/mo) | Not verified |
| Cheaper paid tier below | Go, $8 | None | AI Plus, $4.99 |
*Claude Motion makes code-based MP4 animations on Team and Enterprise plans only; it isn’t a video model.
Free plans differ more:
- ChatGPT Free: unlimited everyday text chats on GPT-6 Luna, limited image creation and deep research, but only a 27K-token context window.
- Claude Free: Sonnet with up to 1M tokens of context, the strongest default free model by Epoch’s index, but no Research, no image generation and 5 projects.
- Gemini Free: Deep Research and image generation (Nano Banana 2), on a Flash-Lite model with a 32K context window.
Which should you use? A playbook by use case
- Coding: Claude. 75% of days at #1 in Arena coding, 87% in web dev, the top web-dev rating today (Opus 5.5, 1806.9). Start with Claude Pro and Claude Code; for algorithmic or data-heavy work, trial GPT-6 Astra in Codex for a week.
- Writing: Claude. Opus 5.5 is #1 in creative writing (1519.6) and instruction following (1521.4). Gemini 4 Argon, within the margin of error, makes a strong second opinion.
- Research: toss-up (Claude by a nose). On today’s models the three are within 0.05 points on our 10-point sub-score. Use Gemini for fact-heavy lookups, ChatGPT for web-search answers, Claude for expert material.
- Math: ChatGPT. GPT-6.1 Sol scores 93.7% on FrontierMath Tiers 1–3 and 100% on Tier 4. Claude has more days at #1 on Arena math (191 vs 132), but that’s a vote, not a test.
- Budget: ChatGPT. Go is $8, and GPT-6 Luna ($0.20) and GPT-6.1 Sol ($4) tie for the cheapest API models at their levels. Google AI Plus is cheaper at $4.99, on a Flash model.
- Business teams: ChatGPT. Same seat price as Claude Team, with major incidents on less than half as many app days. Give engineers Claude seats where code quality beats uptime.
- Free plan: ChatGPT (just). 3.06 checklist points to Gemini’s 3.00 and Claude’s 2.50. Free Gemini for research and images, free Claude for long documents.
- Images and video: Gemini. The only one with native video generation and image generation on every plan.
The bottom line
“ChatGPT vs Claude vs Gemini?” was easy in 2024, when OpenAI simply led. Not anymore.
Claude tops our scorecard because it leads in coding and writing, the work people pay for most, but its reliability is the weaker of the two we can measure fairly. ChatGPT is the steadiest and strongest on hard maths, yet has fallen behind in human preference. Gemini is #1 on today’s leaderboard with the most features, but trails badly in web development.
All three sell the same $20 plan. Pick the one that fits your main job, and keep a free account on another for second opinions.
We’ll update the scorecard quarterly. The full dataset is below.
Methodology
Unit of comparison. Each company’s current lineup, verified on the official model pages on October 25, 2026: GPT-6 Astra, GPT-6.1 Sol and GPT-6 Luna; Claude Fable 5.1, Opus 5.5, Sonnet 5.5 and Haiku 5.5; Gemini 4 Argon, Gemini 3.8 Flash and Gemini 3.5 Flash-Lite. Each company is credited with its best current model on each metric.
Current models only. On LMArena, each company is credited with its best entry still available to customers on October 25, 2026, per the three companies’ deprecation pages. That can be an older model still on sale: GPT-5.6 Sol for OpenAI overall, or Claude Fable 5 (active; suspended only from June 13 to July 1, 2026) in coding, expert and vision. Retired models are skipped: GPT-5.2 Chat (shut down August 10, 2026), Gemini 3.7 Flash and 3.5 Flash (deprecated October 8, 2026, requests rerouted) and Gemini 3 Pro. That changed three current entries and no scorecard input. Ranks are positions on the full public board. Historical “days at #1” counts are unchanged, so past leaders include since-retired models such as GPT-5-high.
Data sources.
- LMArena: Hugging Face dataset
lmarena-ai/leaderboard-dataset(CC-BY-4.0), downloaded October 25, 2026, default view (raw ratings before May 16, 2025, style-controlled after). “Days at #1” credits each snapshot’s top model until the next snapshot. - Epoch AI Benchmarking Hub and Capabilities Index (CC-BY 4.0), downloaded October 25, 2026; Epoch’s own runs kept separate from results it compiles.
- Lab-published scores from launch pages and model cards, shown with attribution but not scored.
- Status pages: status.openai.com and status.claude.com (full histories), Google AI Studio’s feed, and the Google Cloud and Workspace dashboards (rebuilt from 21 Wayback snapshots). Severity is normalised to the Atlassian scale.
- Plans, features and API prices from official pages (read October 25, 2026), Wayback snapshots and The Brief Script AI Price Index (verified October 24, 2026). Blended API price = (3 × input + output) ÷ 4, per million tokens.
Scoring. Each metric is scored 0–10 against the best of the three (10 × value ÷ best, or 10 × best ÷ value when lower is better). LMArena gaps are converted to an expected head-to-head win rate (Elo) and scored 10 × win rate ÷ 50%. ECI counts as a tie when 95% confidence intervals overlap, as all three do. Blocks of related metrics count equally within a pillar. Benchmarks qualify only if all three have a current model scored and results aren’t saturated (OTIS Mock AIME excluded) or near zero (FrontierMath-Erdos excluded). Pillars are weighted 30/25/15/15/15.
Google reliability isn’t scored (coverage isn’t comparable); its overall re-weights the other four pillars. Scoring it 0 or 10 doesn’t change first place.
Features are coded from official feature tables (1 = available, 0.5 = limited, 0 = not). The free-plan model item assumes Claude Free runs Sonnet 5.5 and Gemini Free runs Gemini 3.5 Flash-Lite; neither company states the version, so this is our inference.
Use-case verdicts use the metrics relevant to each job, plus a “today-only” version without the days-at-#1 track record. Where they disagree (math and vision), the verdict follows today’s models.
Robustness. 20 named scenarios (alternative weights, leaving out each pillar, two other normalisations, no blocks, Google’s post-promotion API prices, adding Terminal-Bench 4.0, excluding Anthropic’s access suspension) plus 10,000 random weightings (flat Dirichlet, seed 20261025).
Limitations.
- Arena ratings measure preference, not accuracy, are sensitive to style and effort settings, and changed methodology mid-period. Snapshots arrive every 1 to 10 days, so day counts are approximate.
- Status pages measure disclosure. Anthropic posts per model, OpenAI per feature, Google sparingly; durations are defined differently, and AI Studio’s severity levels are mapped by inference.
- Benchmarks lag launches. Epoch has no GPQA run for Claude Fable 5.1 yet and still labels Gemini 4 Argon “Limited access”. OpenAI published GPT-6.1 Sol’s results only as charts.
- Usage limits are mostly relative (“5x Pro”, rolling 5-hour windows), so we couldn’t score usage per dollar.
- Some prices are promotional (Gemini 4 Argon and 3.8 Flash on the API). Google’s $199.99 annual AI Pro price is unverified and not counted.
- Lineups change fast. This is an October 25, 2026 snapshot.
Download the data
Free to reuse with attribution (CC-BY 4.0; LMArena and Epoch AI data keep their own CC-BY licences).
- briefscript_ai_assistant_scorecard.csv: every metric, raw value and 0–10 score.
- briefscript_lmarena_days_at_1.csv: days at #1 by arena and category.
- briefscript_lmarena_current_available.csv: each company’s best still-available entry per arena today, with model availability sources.
- briefscript_status_incidents_summary.csv: incidents, major/critical days and hours, median durations.
- briefscript_ai_plans.csv and briefscript_ai_features.csv: plans, prices, limits and features, with sources.
Cite this report: The Brief Script, “The Brief Script AI Assistant Scorecard,” October 2026. thebriefscript.com/gemini-vs-chatgpt-vs-claude/
FAQ
Is Gemini better than ChatGPT? On today’s LMArena leaderboard, yes: Gemini 4 Argon is #1 overall (1517.2), OpenAI’s best entry 21st (1485.1), and Gemini has more features. ChatGPT is ahead on measurable reliability, hard maths and budget. Our scorecard has Gemini 81.5, ChatGPT 80.9: effectively a tie.
ChatGPT vs Claude: which is better? Claude scores higher overall (86.5 vs 80.9), mainly on coding and writing. ChatGPT is clearly more reliable (API major or critical incidents on 41 days in 18 months, against 157 for Claude) and leads on hard maths.
Claude vs Gemini: which should I use? They’ve split overall #1 almost evenly over 18 months (240 days vs 234). Choose Claude for coding and writing; Gemini for images, video, fact-heavy research and the cheapest paid plan ($4.99).
Is Claude or ChatGPT better for coding? Claude, on balance: #1 in Arena coding for 75% of the past 18 months and 32.6 points ahead in web development today. On four independent coding tests, though, they win two each.
What is the best AI model in 2026? There isn’t one. On Epoch’s index, Claude Opus 5.5 (168.83) and GPT-6 Astra (168.81) are tied; on human votes, Gemini 4 Argon leads; Claude tops our scorecard. It depends on whether you prioritise coding, reliability, maths or features.
Which AI chatbot has the best free plan? It’s close. ChatGPT Free has unlimited everyday chats, Gemini Free has Deep Research and images, and Claude Free has the strongest model and up to 1M tokens of context.
Gemini vs ChatGPT: which is cheaper? At the ~$20 tier they cost the same (Google AI Pro $19.99, ChatGPT Plus $20). Below it, Google AI Plus is $4.99 and ChatGPT Go is $8. On the API, both sell a frontier-level model for $4 per million blended tokens, but Gemini 4 Argon’s promotional price doubles to $8 on December 1, 2026.
Is Claude or ChatGPT more reliable? ChatGPT. From April 2025 to October 2026, OpenAI’s API had a major or critical incident on 41 days and Anthropic’s on 157. Anthropic resolves incidents faster (median 1.10 hours vs 1.65).
Is Claude better than Gemini for coding? Yes, on most evidence. Claude beats Gemini 4 Argon on all four independent coding tests we track, leads web development by 132.7 points, and scores 9.9 vs 5.8 on our coding pillar. Gemini currently leads Arena coding by just 1.0 point.